MiniMax H3 4× Faster for Free: Turbo LoRA, Cache & Sage Attention
Turbo is not a MiniMax accelerator — it is a third-party distilled LoRA. The official Comfy-Org packaging loads exactly three Turbo files, and each file's step count and shift pair are bound to it rather than tuned freely. Everything measured below comes from one RTX 3060 12GB.
MiniMax H3 tool
Which speed-up fits your card?
Turbo LoRA, 4 steps ~4.12x faster
minimax_h3_fl2v_turbo_4step_v1.0_768p_comfyui_bf16.safetensors- The acceleration-stack speedup divides the whole formula, fixed overhead included, even though model load, text encode and VAE decode do not get faster with fewer steps. At production sizes sampling is about 98% of the run and this is right to 0.25%; at the smoke size fixed overhead is about 90% and it is not. Dividing only the sampling term instead would break the Turbo A/B, the hardest same-machine comparison this project has.
- Cache-node speedups were measured on the un-accelerated 20-step baseline alone. This site has never measured a stack × cache combination on one machine, so the factors must not be multiplied — the cache row of the technique table, not this recommendation, is where cache advice lives.
- This site — The A/B, in full — Turbo off 2,175.5 / 2,176.2 s @20 steps vs Turbo on 526.7 / 528.9 / 528.6 s @4 steps — same machine, same seed, same card. Range 4.113–4.132.
The eleven levers, and what is known about each
- Turbo LoRAmeasured
Load the file through LoraLoaderModelOnly. File name, step count and shift travel as one set: 4step v1.0 = 4 steps, shift 6/3; 8step v1.0 = 8 steps, shift 12/3.
LoraLoaderModelOnlyminimax_h3_fl2v_turbo_4step_v1.0_768p_comfyui_bf16.safetensorsminimax_h3_fl2v_turbo_8step_v1.0_comfyui_bf16.safetensors(source · source · source · source) - LightX2Vreported
Loaded through the same LoraLoaderModelOnly node; the reported run used the 4step FL2V Turbo file.
LoraLoaderModelOnlyminimax_h3_fl2v_turbo_4step_v1.0_768p_comfyui_bf16.safetensors(source · source) - FastVideo VSAreported
BlockSparseAttention node, method vsa, keep_percent 10 — requires FastH3 model weights; ComfyUI raises an error for any other model.
BlockSparseAttentionmethod=vsakeep_percent=10(source · source · source · source · docs (2026-09-18)) - Cache nodesmeasured
Custom nodes installed under ComfyUI/custom_nodes, then restart ComfyUI. The flags above are each pack's registered node name, not necessarily the README's name.
MiniMaxH3TeaCacheApplyMiniMaxH3FirstBlockCacheMiniMaxH3AdaptiveCacheH3CombinedAccelerationTESpeedMiniMaxH3(source · source · source · source · source)Conflicts: Turbo LoRA can stack; FastVideo VSA cannot stack; SLA attention cannot stack;
- SageAttentionnot tested
Start ComfyUI with --use-sage-attention; the sageattention package must be installed first (pip install sageattention).
--use-sage-attentionpip install sageattention(source · source)Conflicts: Attention backend cannot stack;
- Attention backendnot tested
ModelAttentionBackend node, or the --use-pytorch-cross-attention / --use-ck-attention flags — one mutually exclusive attention group in ComfyUI's argument parser.
ModelAttentionBackend--use-pytorch-cross-attention--use-ck-attention(source · source · docs (2026-09-18))Conflicts: FastVideo VSA can stack; SLA attention can stack;
- SLA attentionreported
BlockSparseAttention node, method sla, keep_percent 10 — use only with LoRAs distilled for this pattern.
BlockSparseAttentionmethod=slakeep_percent=10(source · source · source · docs (2026-09-18)) - Chunked feedforwardnot tested
No official enablement path verified (ComfyUI source / official docs, checked 2026-09-18).
- Fast VAE decodenot tested
No official enablement path verified (ComfyUI source / official docs, checked 2026-09-18).
- Spectrumnot tested
No official enablement path verified (ComfyUI source / official docs, checked 2026-09-18).
- Multi-GPUnot tested
MultiGPU_WorkUnits node (advanced/multigpu); --cuda-device picks the devices. The official docs note that speed-based workload distribution is not yet implemented.
MultiGPU_WorkUnitsmax_gpus=2--cuda-device(source · source · docs (2026-09-18))
Not fal's hosted H3 Max Turbo
Same word, different thing. fal's H3 Max Turbo is a hosted preview endpoint from September 2, 2026 that serves a distilled H3 Max at half the Max price, and its API schema had no LoRA input when checked on September 3, 2026. This page covers the local Turbo LoRA files you load in ComfyUI on your own GPU; neither replaces the other. If you came looking for the hosted one, read the hosted H3 Max guide; its timings and its per-second rate are published on fal’s own model card.
Turbo LoRA: what it is, how to turn it on, what it stacks with
What it is. A Turbo LoRA is a distilled LoRA file loaded on top of the open-weight MiniMax H3 so that sampling runs in 4 or 8 steps instead of the base template's 20. It is a third-party distillation, not a MiniMax accelerator, and it shortens the sampling segment only — the claimed-versus-measured section says what that leaves unchanged.
How to turn it on. Load one file from the file table through a LoraLoaderModelOnly node, then set the step count and both shift schedules from that same row. For T2V and I2V the selector above works with the two FL2V files: minimax_ runs 4 steps at shift 6 / 3, and minimax_ runs 8 steps at shift 12 / 3. The B side of the A/B below was built exactly this way: the A-side workflow plus a LoRA loader, a shift node and the step change. The upstream project publishes no strength value; 1.0 is this site's own choice. For R2V the selector recommends no Turbo file at all — the only Ref2V Turbo file was trained on 544p mixes, which is why the A/B used FL2VA.
What it stacks with. The selector's Turbo row lists no conflicts, because no ComfyUI source or official document checked for it states one. The one documented relation comes from the cache side: the AdaptiveCache README says Turbo LoRA and its cache node run together on the execution path, and in the same line declines to call the pair verified lossless because its own Turbo quality test still has an unresolved variable. Two limits hold on this page. The selector's LightX2V row loads the same 4-step FL2V file through the same node — it is this series under its upstream project's name, not a second LoRA to add on top. And the two Turbo series do not share parameters: the series table is a rule, not a suggestion.
What the data says. Measured here on one RTX 3060 12GB, the 4-step 768p file against no LoRA gave a paired wall-time range of 4.113×–4.132× — Turbo off 2,175.5 s / 2,176.2 s at 20 steps, Turbo on 526.7 s / 528.9 s / 528.6 s at 4 steps — with no reliable peak-VRAM reduction; the full A/B lists every condition. The 8-step file has not been run here, so no speed-up is published for it: the step ratio 20 / 8 is arithmetic, not a measurement. No Turbo × cache pair has been measured on one machine either, so this range is never multiplied by a cache node's figure.
Sources. The node: LoraLoaderModelOnly in ComfyUI nodes at commit 3c80da7f…. Files, steps and shift: the ModelTC README rows for the 4-step 768p file and the 8-step file, and the Comfy-Org loras/ tree at dc559027…, re-checked 2026-09-18. The cache relation: AdaptiveCache README, line 328. The numbers: this page's A/B.
The three files you can actually load in ComfyUI
These are the only three Turbo LoRA files repackaged for ComfyUI in the Comfy-Org repository as of 2026-08-17. Each row is one file with the task it serves, the step count its upstream specification fixes, and the two shift schedules that travel with it. Third-party conversion repositories distribute other Turbo files under different names — where those download links actually point is the troubleshooting finding below.
Checked against the Comfy-Org repackage at pinned revision dc559027… and the ModelTC parameter README at commit a7e148b8… on 2026-08-18, re-checked 2026-08-20.
File (Comfy-Org loras/) | Task | Official steps | Shift video / audio |
|---|---|---|---|
File (Comfy-Org loras/)minimax_ | TaskT2V / I2V | Official steps8 (4 also allowed upstream) | Shift video / audio12 / 3 |
File (Comfy-Org loras/)minimax_ | TaskT2V / I2V | Official steps4 | Shift video / audio6 / 3 |
File (Comfy-Org loras/)minimax_ | TaskR2V | Official steps4 | Shift video / audio12 / 3 |
Four rules that travel with the table.
- The step count belongs to the selected LoRA's upstream specification, not a free dial. The circulating "6–8 steps" advice is off-specification for this series.
- Video and audio shift are two independent schedules. Set both, not just the video one.
- File name, steps and shift are used as a set. A partial combination is an invalid configuration, not a variation.
- LoRA file names use
fl2v/ref2vwith no trailinga. Diffusion weights usefl2va/ref2va. The two spellings are not interchangeable.
Sources: the pinned Comfy-Org loras/ repackage (checked 2026-08-20) and the ModelTC README at commit a7e148b8… (checked 2026-08-18). Download entrance changes the license track — see Licenses and the file-to-license map.
The Turbo download that points at the wrong repository
Hard-coded by third-party template hubs such as RunComfy
minimax_The download link those templates ship points at the wrong repository. RunComfy's actual anchor targets Comfy-, and that exact URL returns 404. Separately, the official loras/ tree carries only the three _ files in the table above and has no same-named file. If the download fails, the problem is the template's link, not your network or your ComfyUI install.
The same-named file does exist somewhere else: the third-party conversion repository drbaph/ at revision 4728c77e… has served it since 2026-08-06 (introducing commit b6ac1b80…), and the pinned copy measures 620,285,648 bytes. That repository is a derivative-conversion distribution, not a third training series: its README describes this file as a pruned/curve-form compatibility conversion of Larryvrh's Turbo LoRA, and the file's own metadata is a partial conversion (partial_, target MiniMax-) carrying a verbatim warning: "All AdaLN LoRA adapters were removed because the source targets input dimension 2688 while the pruned model targets dimension 8. Four-step distillation behaviour may be degraded or broken." It is not an official equivalent of anything in the table above.
How it was checked (2026-08-27): the RunComfy public workflow page and workflow JSON were read directly; the page's download anchor targets the exact Comfy- / resolve URL, which returns 404, while the JSON cites the same file name; the official loras/ tree was checked separately; the drbaph pinned file page resolves at 620,285,648 bytes; and the conversion metadata above was read from the file's own header.
Practical routing: use one of the three official files with its bound parameters, and only reach for the drbaph conversion if you specifically run the pruned-curve model variant it targets — its parameters follow the Larryvrh series rules, and its own warning applies. The symptom-led guide covers the loader errors a missing or misplaced file produces.
Two independent Turbo series
Two unrelated project families publish MiniMax H3 Turbo LoRAs. Their parameters are not compatible across series, and this page's A/B used only the first one.
| Series | Authors / license | Distribution | Headline files |
|---|---|---|---|
| SeriesLightX2V | Authors / licenselightx2v / ModelTC — Apache-2.0 upstream | DistributionUpstream lightx2v/ plus the Comfy-Org repackage (three _ files) | Headline filesThe three files in the table above, ≈1.96 GB each |
| SeriesLarryvrh | Authors / licenselarryvrh, third party — Apache-2.0, verified through the Hugging Face API on 2026-08-19 | Distributionlarryvrh/ at pinned revision 43a74557… plus a companion ComfyUI plugin repository | Headline filesminimax_, ≈780 MB; its README suggests 4–8 steps, strength 1 and shift 12/3 for its own files only |
The Larryvrh README values — 4–8 steps, strength 1, shift 12/3 — apply to Larryvrh files only. Carrying them over to any LightX2V file is an invalid configuration, and this page does not do it anywhere.
Claimed versus measured
The claimed column records what this site could verify about each circulating claim — not the claim restated as given. The measured column carries this site's own raw values. Nothing is computed between the two columns.
| Claimed (circulating) | What the source check found | Measured here |
|---|---|---|
| Claimed (circulating)"up to 5×" | What the source check foundThe pinned ModelTC README at commit a7e148b8… does not contain it. The closest sourced wording is the Larryvrh README at revision 43a74557…, checked 2026-08-19: "as few as 4 sampling steps instead of the usual ~20 — a ~5× sampling speedup" — a step-count ratio with no hardware, wall time or test date. No source states the number with a hardware environment and test date, so it stays unpublished as a claim (re-checked 2026-08-27). | Measured hereSame-machine paired wall-time range 4.113×–4.132× — Turbo off 2,175.5 s / 2,176.2 s at 20 steps against Turbo on 526.7 s / 528.9 s / 528.6 s at 4 steps (full A/B). |
| Claimed (circulating)"runs better on 8G cards" | What the source check foundRecorded the same way: no source, environment or date on file, so it is not published as a verified claim. | Measured hereThis run did not establish a reliable peak-VRAM reduction. All three Turbo peaks were above 8,192 MiB; this was not an 8GB-card test. |
Why the two columns move differently: fewer steps shrink the sampling segment only. VAE decode, text encoding and model loading do not scale with the step count, so wall time fell here while peak VRAM stayed in the same band. The cache-node family measured the same direction for a different lever — the cache-node page owns that evidence, and this page does not restate its tables.
The A/B, in full
Both sides ran the same prompt, seed 20260820, 1344×768 canvas, 124 frames at 24 fps, the same res_ sampler, simple scheduler, BasicGuider, audio path and the same four base weights, on the same physical GPU 0 and software build. Steps and shift differ because they are part of what was tested: each side runs its own file's bound values, and both are printed.
| Setting | A · Turbo off | B · Turbo on |
|---|---|---|
| SettingLoRA | A · Turbo offnone | B · Turbo onminimax_ |
| SettingSteps | A · Turbo off20 | B · Turbo on4 (this file's bound specification) |
| SettingShift video / audio | A · Turbo offthe base template has no shift node — not explicitly set | B · Turbo on6 / 3, two independent schedules |
| SettingLoRA strength | A · Turbo offnot applicable | B · Turbo on1.0 — this site's value; the upstream project publishes no recommendation, and none is invented here |
Why only this file gives a clean comparison at 1344×768: the 4-step v1.0 768p LoRA was trained at exactly 1344×768. The only Ref2V Turbo file is the 4-step v0.1 trained on 544p mixes, so running it at 768p would be a training/inference mismatch rather than an equivalent A/B.
| Measurement | A · Turbo off | B · Turbo on |
|---|---|---|
| MeasurementComfyUI wall time | A · Turbo off2,175.5 s / 2,176.2 s | B · Turbo on526.7 s / 528.9 s / 528.6 s — median 528.6 s, range 526.7–528.9 s, no mean taken |
| MeasurementPeak VRAM (GPU 0) | A · Turbo off11,023 / 10,863 MiB | B · Turbo on11,185 / 10,479 / 10,895 MiB |
| MeasurementOutput repeats | A · Turbo offboth complete MP4s byte-identical | B · Turbo onall three complete MP4s byte-identical |
On this same RTX 3060 workload, the paired wall-time range was 4.113×–4.132×. That ratio is arithmetic between this site's own measurements on one machine: A-side 2,175.5 s / 2,176.2 s against B-side 526.7 s / 528.9 s / 528.6 s, at 20 versus 4 steps. It is published as a pairing and never averaged into a single number, and it is never compared against the unverified "up to 5×" text.
Full test conditions — A side, Turbo off
- GPU / host — Physical GPU 0, NVIDIA GeForce RTX 3060 12GB; Intel Core i9-10850K KVM guest, 16 vCPU, 48,153 MiB VM RAM, no swap.
- Software — Ubuntu 24.04.4; driver 580.173.02; CUDA 13.0; Python 3.12.3; PyTorch 2.13.0+cu130; ComfyUI 0.31.0 at
bf4c9a08…; comfy-aimdo 0.4.10, cache none, SageAttention absent, compile off. - Workflow / revision —
video_; API workflow SHA-256minimax_ h3_ t2v .json@7837633a… 1b083dfa1a4540b3805b998a66f5585f4337d5fbe14b441ca7ac0a2e1bf545a2. - Prompt / seed — Official pinned prompt, SHA-256
c628dfa9b3e7b4e6e406cf609d4ae7537566b8b69cf84d63322886de48803dc4; seed20260820. - Canvas / frames / fps — 1344×768 · 124 frames · 24 fps · native audio on.
- Weights — FL2VA INT8 ConvRot, Qwen3-VL encoder, video and audio VAE — the four fixed files of the baseline record; no LoRA.
- Steps / shift / strength — 20 steps; no shift node in the base template, not explicitly set; no LoRA strength.
- Test IDs —
SITE-and3060- FL2VA- T2V- GPU0- B1 …-, measured 2026-08-19.RUN2
Full test conditions — B side, Turbo on
- GPU / host — Same physical GPU 0, NVIDIA GeForce RTX 3060 12GB; same host; GPU 1 stayed 113→113 MiB on all three runs,
contaminated=false. - Software — Identical build to the A side: Ubuntu 24.04.4, driver 580.173.02, CUDA 13.0, PyTorch 2.13.0+cu130, ComfyUI
bf4c9a08…; ComfyUI process restarted before each run. - Workflow / revision — B-side API workflow SHA-256
735972cab03bca6fb010da173b2b51e42b3cadd3e107188e51005e157b14d10a, byte-identical across all three runs; derived from the A-side file by adding the LoRA loader, the shift node and the step change. - Prompt / seed — Same prompt bytes, SHA-256
c628dfa…dc4; same seed20260820; same canvas, frames and fps. - LoRA —
minimax_— 1,956,192,992 bytes, SHA-256h3_ fl2v_ turbo_ 4step_ v1.0_ 768p_ comfyui_ bf16 .safetensors c396a9a06f58399e9df9754b18299818d84a2ddd371724ba48fe4a41221437dc, from the Comfy-Org repackage at pinned revisiondc559027…. - Steps / shift / strength — 4 steps; shift video 6 / audio 3 as two independent schedules; strength 1.0 — this site's value, the upstream project gives no recommendation.
- Output — Three complete MP4s of 2,650,811 bytes, all SHA-256
e3f19c0d8c4ea937cf9ffaca66739bb73b3ca1ef2875dfae7aa6a1c72f260bc2— byte-identical repeats. - Test IDs —
SITE-,3060- FL2VA- T2V- TURBO- GPU0- B1 …-,RUN2 …-, measured 2026-08-20; a fourth orchestration failure that never entered inference is retained in the ledger.RUN3- RETRY1
Full record: every retained run, including the smoke run and the retained orchestration failure, lives in the run ledger. This is a site_ pair, not a reproduction of any community claim.
Same seed, side by side
Each strip below places the Turbo-off frame on the left against the Turbo-on frame on the right at the same frame index, generated from the two runs above at the same seed. The strips are presented as they were produced; this page assigns no quality score, winner or preference to either side, and the labels you see are part of the source images.
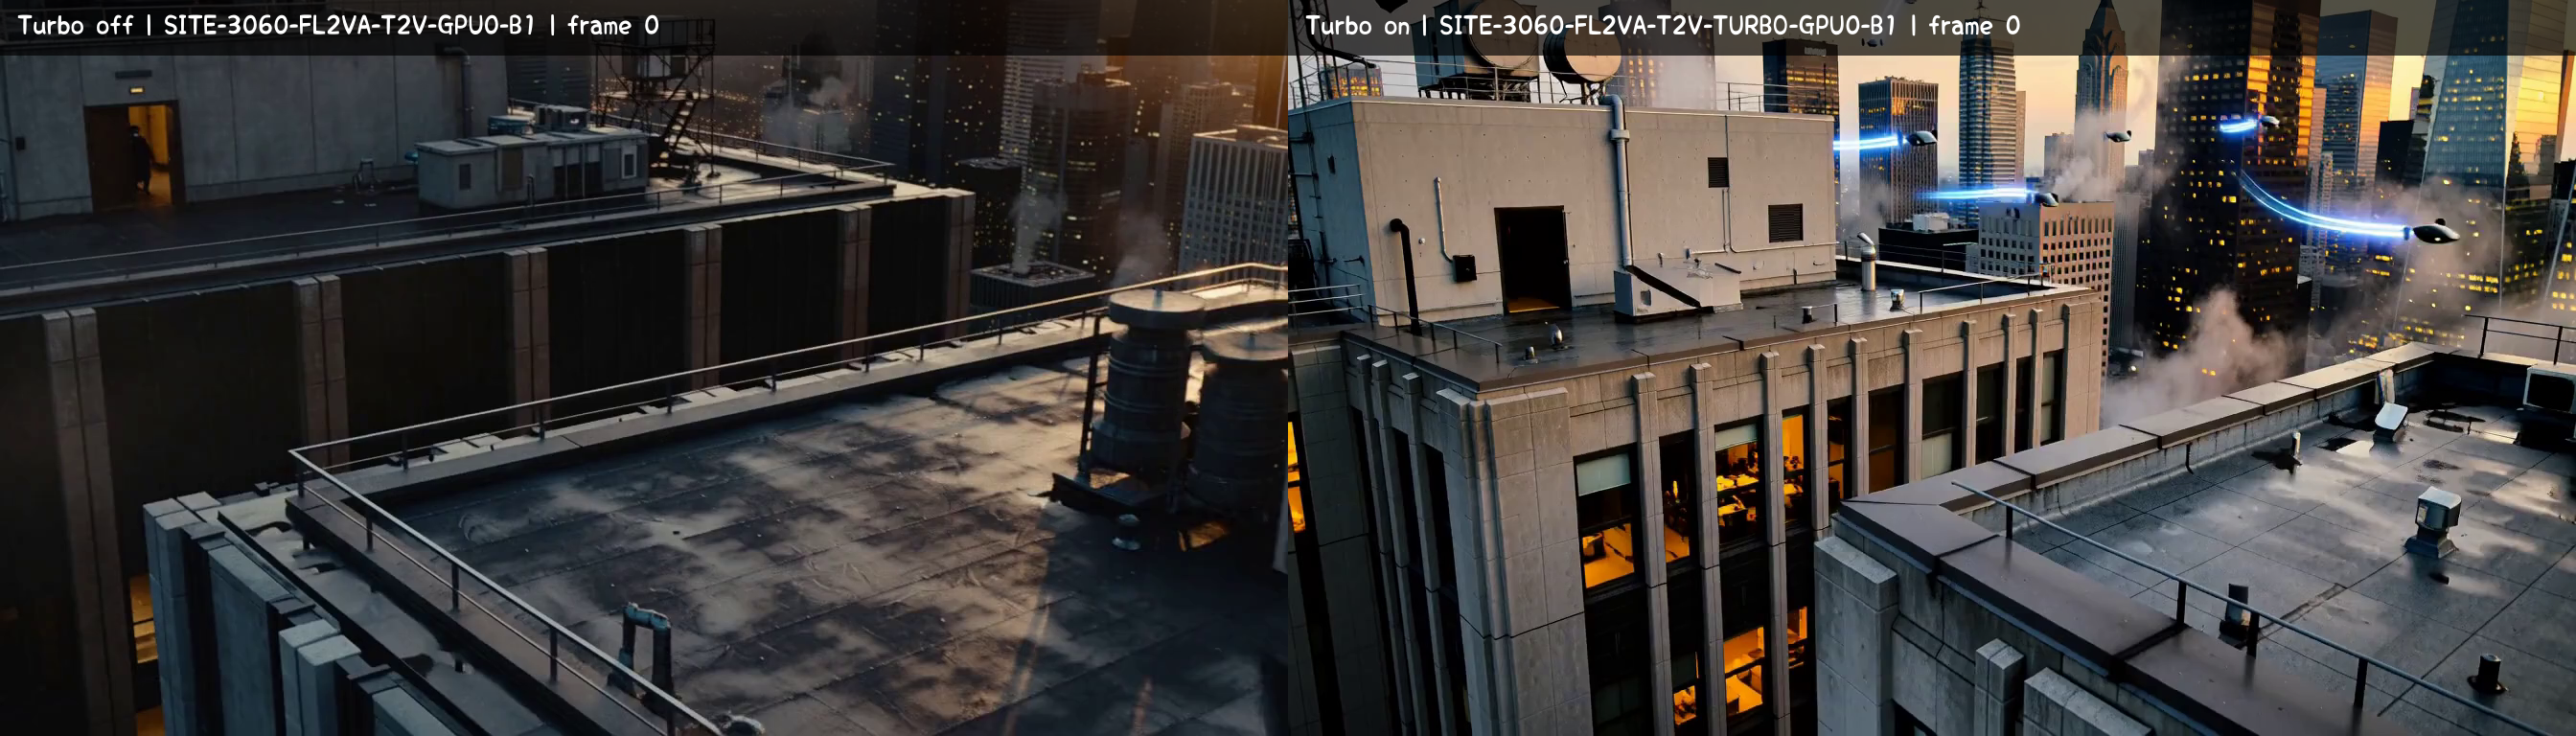
Frame 0 of 124 · left: Turbo off · right: Turbo on · seed 20260820 · 1344×768
Machine-generated content. Both frames are MiniMax H3 model output from the measured runs SITE- (Turbo off) and SITE- (Turbo on) at seed 20260820. The people and scene are synthetic. Model Outputs carry territorial restrictions under the MiniMax H3 Community License — read the license map before reusing them.
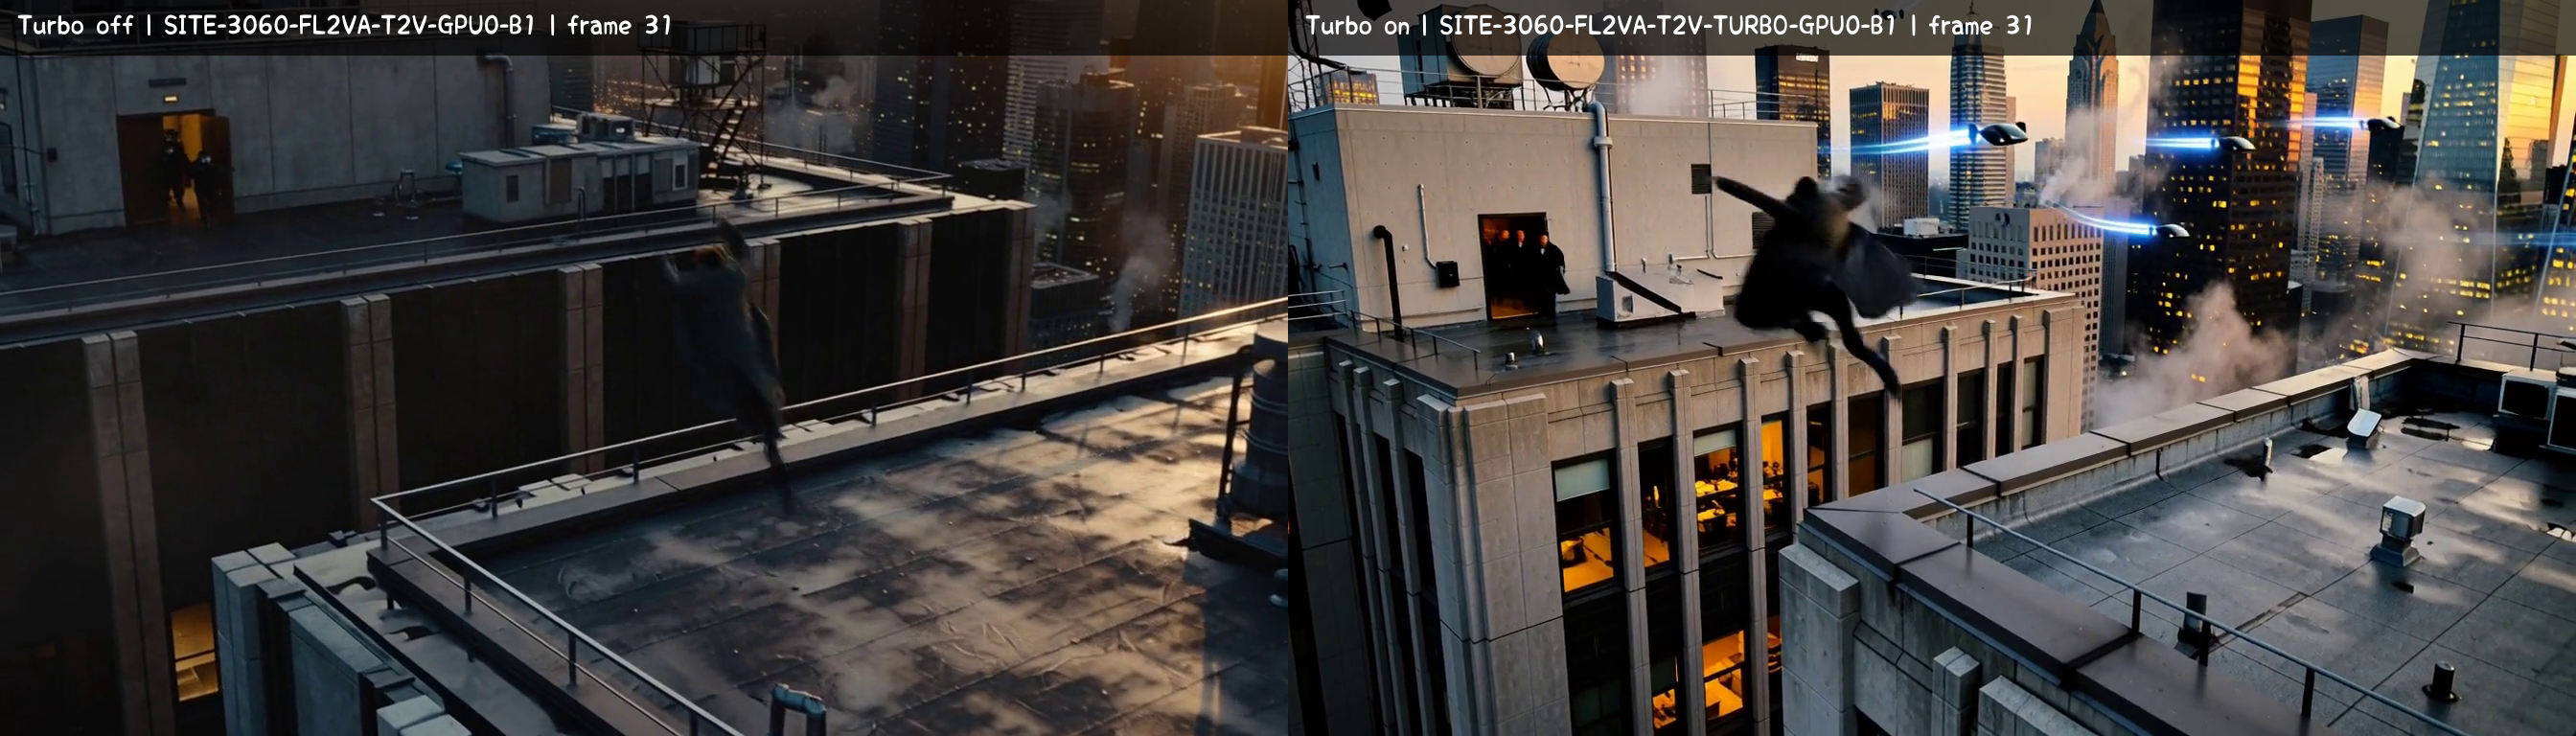
Frame 31 of 124 · left: Turbo off · right: Turbo on · seed 20260820 · 1344×768
Machine-generated content. Both frames are MiniMax H3 model output from the measured runs SITE- (Turbo off) and SITE- (Turbo on) at seed 20260820. The people and scene are synthetic. Model Outputs carry territorial restrictions under the MiniMax H3 Community License — read the license map before reusing them.
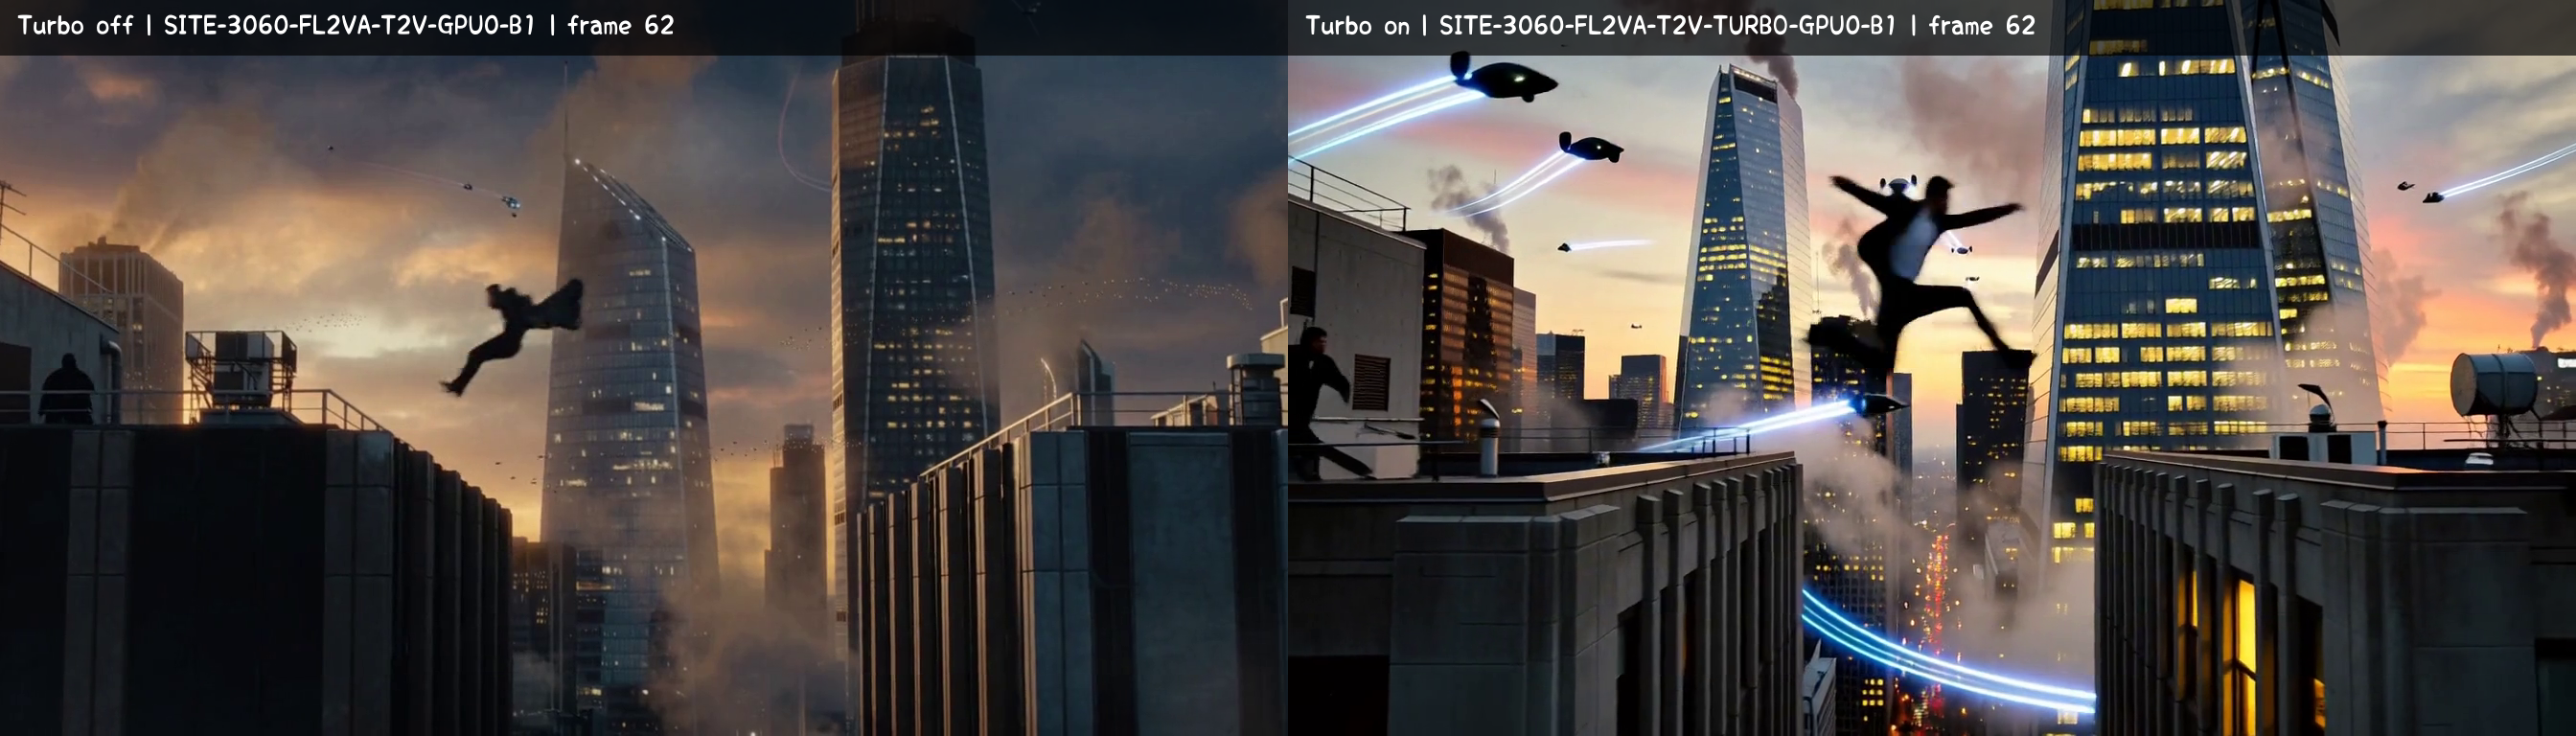
Frame 62 of 124 · left: Turbo off · right: Turbo on · seed 20260820 · 1344×768
Machine-generated content. Both frames are MiniMax H3 model output from the measured runs SITE- (Turbo off) and SITE- (Turbo on) at seed 20260820. The people and scene are synthetic. Model Outputs carry territorial restrictions under the MiniMax H3 Community License — read the license map before reusing them.
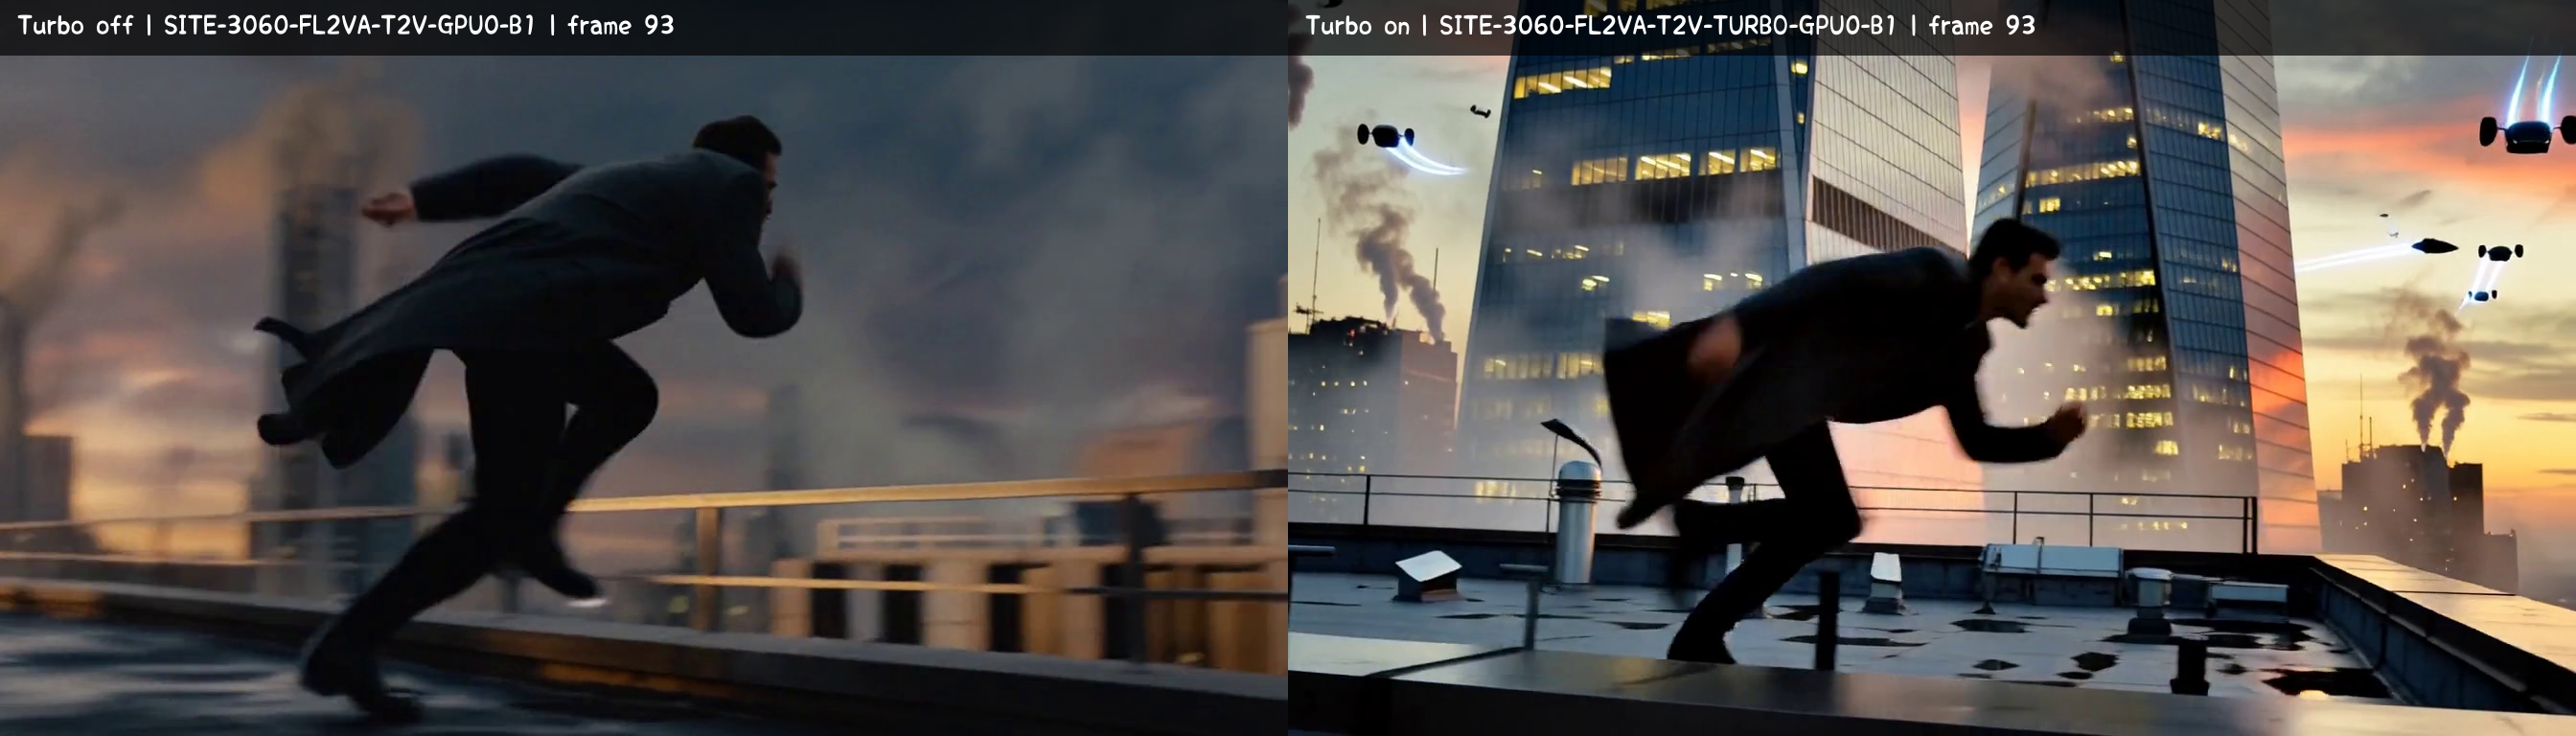
Frame 93 of 124 · left: Turbo off · right: Turbo on · seed 20260820 · 1344×768
Machine-generated content. Both frames are MiniMax H3 model output from the measured runs SITE- (Turbo off) and SITE- (Turbo on) at seed 20260820. The people and scene are synthetic. Model Outputs carry territorial restrictions under the MiniMax H3 Community License — read the license map before reusing them.
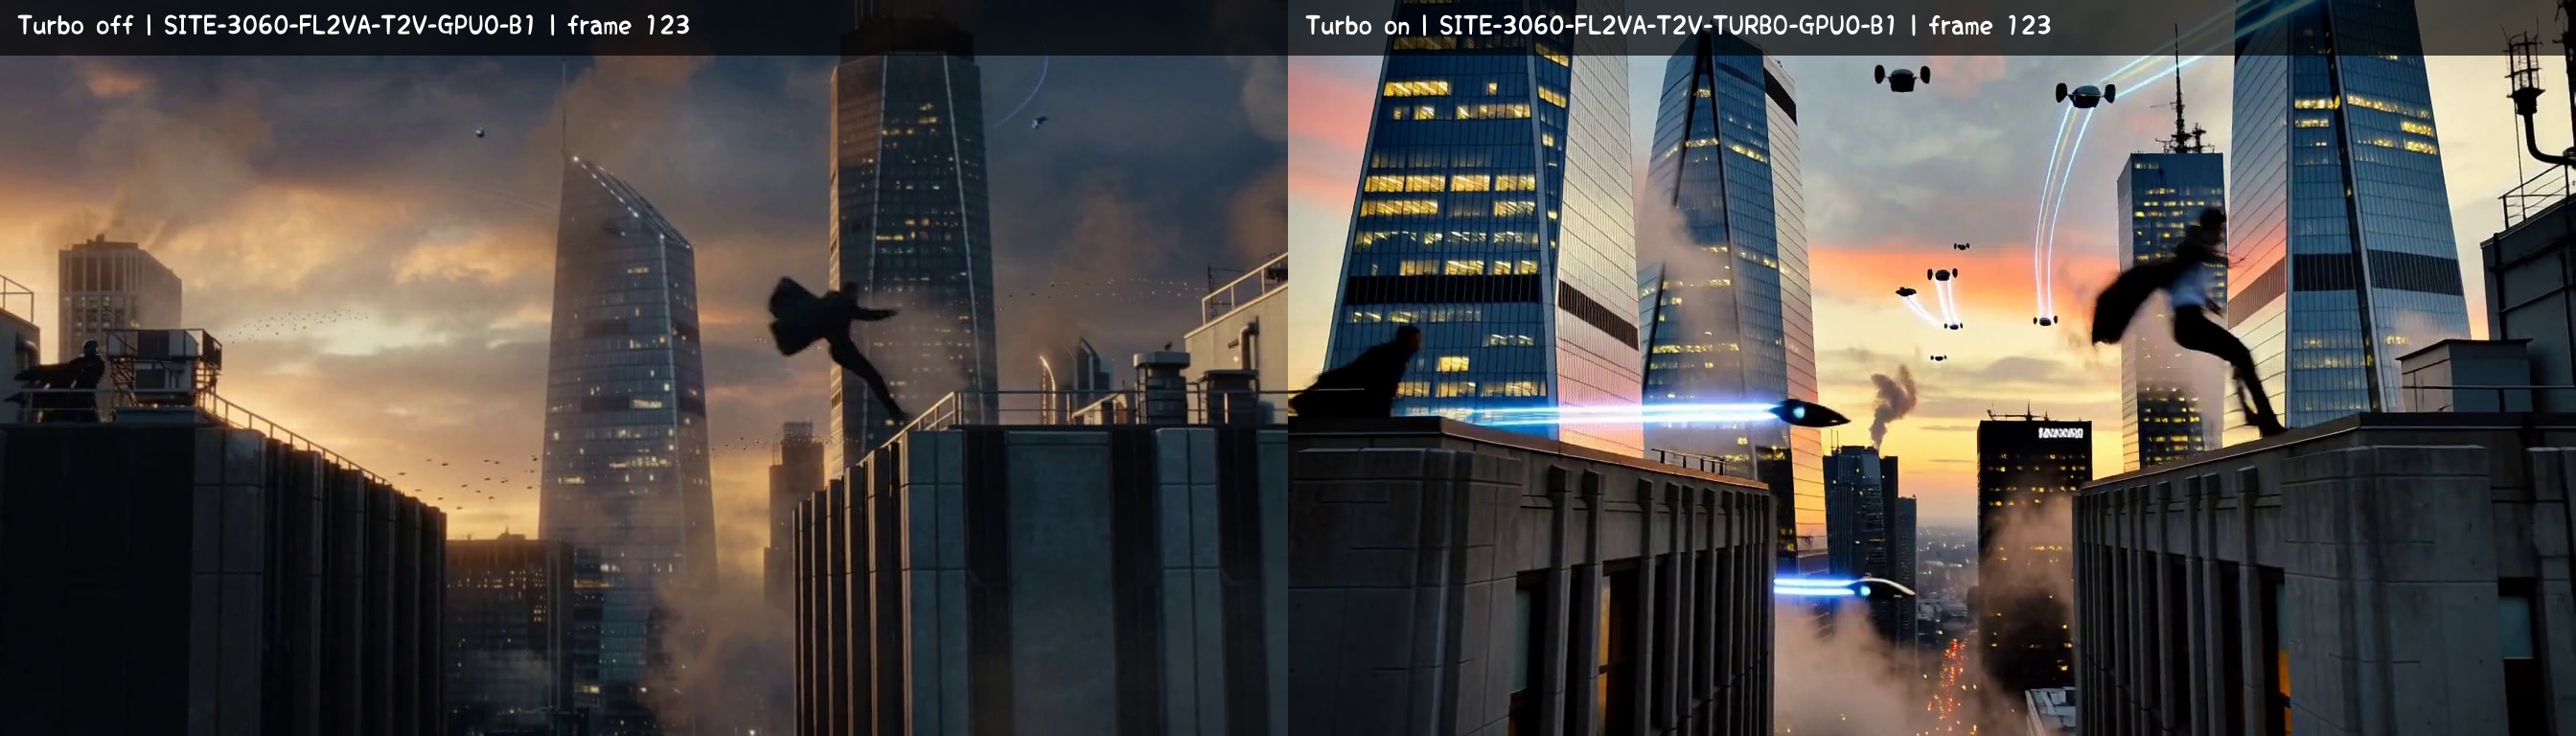
Frame 123 of 124 · left: Turbo off · right: Turbo on · seed 20260820 · 1344×768
Machine-generated content. Both frames are MiniMax H3 model output from the measured runs SITE- (Turbo off) and SITE- (Turbo on) at seed 20260820. The people and scene are synthetic. Model Outputs carry territorial restrictions under the MiniMax H3 Community License — read the license map before reusing them.
What you are allowed to do with these files
1 · The distilled LoRA itself
Apache-2.0 by lightx2v / ModelTC, the upstream authors of the LightX2V series. The Larryvrh series is separately Apache-2.0, verified through the Hugging Face API on 2026-08-19. Upstream terms were checked at revision ec01fa4c… on 2026-08-20.
2 · The download entrance and base model
The Comfy-Org repackage repository declares license: other / minimax-h3-community-license metadata at repository level, and the base model carries the MiniMax H3 Community License. Which terms you accept depends on which entrance you download from — the file-to-license map keeps them apart.
3 · The territory clause
The base license grants use, reproduction, modification, distribution and display only in the Applicable Territories — the world excluding the EU, the UK, the Republic of Korea and the United States. Read the source map for the clause text.
Separate · The text encoder
The Qwen3-VL-32B encoder is Apache 2.0 per the base license's Additional Note. That track is separate from the three above and is not merged into them.
This page deliberately avoids the phrases "official model license" and "MiniMax's official accelerator": provenance checks show the Turbo LoRAs are third-party distillations, and merging the license tracks would hide who actually grants what.
If it does not work
The workflow download 404s
If a template asks for minimax_, RunComfy's Comfy-Org / link is dead — the template points at the wrong repository. Do not replace only the file name: either repair the template for the pruned-curve/Larryvrh path described above, or switch the workflow, base model, LoRA, steps and both shift schedules together to a matched official LightX2V set.
Steps do not match the file
Run the step count bound to the chosen file — the table above. Off-specification step counts such as a 6–8-step range are not variations this series supports.
Only video shift was set
Shift is two schedules. If the audio shift is left at its default while the video shift is changed, the configuration is incomplete — set both values from the same row.
The two series got mixed
Larryvrh's strength and shift values do not transfer to LightX2V files. Pick one series, take its whole parameter set, and do not combine — see the series table.
Ref2V Turbo at 768p
The only Ref2V Turbo file is a 544p-trained v0.1. Running it at 1344×768 is a training/inference mismatch, not a supported configuration — see why the A/B used FL2VA.
A different symptom
For loader errors, missing folders or stalls, start from the exact error in the symptom-led guide instead of changing several settings at once.
Cache nodes: what they are, how to turn them on, what they stack with
What they are. Cache nodes are third-party ComfyUI custom nodes that make a run faster by skipping part of the computation during sampling. Unlike a Turbo LoRA, a cache node is code rather than a model file, and each pack comes from an independent author — none of them ships with ComfyUI or with MiniMax H3.
How to turn them on. Put the pack's folder into ComfyUI/ — a git clone there does it — and restart ComfyUI. That is the whole install in every README the selector cites, except that TE-Speed's adds a one-time python patch_ step. The node then appears under its registered name, which is often not the name in the README: MiniMaxH3TeaCache, ApplyMiniMaxH3FirstBlockCache, MiniMaxH3AdaptiveCache, H3CombinedAcceleration and TESpeedMiniMaxH3 are the five the selector lists, as registered names, not as a ranking. The two READMEs that describe placement put the node right after the H3 UNETLoader; where its MODEL output has to go next is the easiest wiring mistake to make, and the cache-node test page walks through it.
What it stacks with. The selector records three relations, all taken from two lines of the AdaptiveCache README. Cache and Turbo LoRA stack: the README says both run together on the execution path, while declining to call the pair verified lossless. Cache and FastVideo VSA, and cache and SLA attention, do not: the README advises against any other node that replaces H3's double_ — another cache, a layer skip or a block patch — because one extension point takes one final implementation, and ComfyUI's Block Sparse Attention, which both of those run through, reaches MiniMax H3 through block patches. The same line advises against a second cache node alongside it. These are one pack's statements about itself, and this page does not extend them to the other four. "Stacks" means the two can run in one graph; it does not mean their speed-ups multiply.
What the data says. Measured on an RTX 3060 12GB with Turbo LoRA off, some cache nodes cut wall time, one changed the output without saving any, and none of them is a way to fit a workflow that does not already fit — the per-node results, the baseline and the check that separates a working node from a merely loaded one are on the cache-node test page and are not repeated here.
Sources. Install and placement: the pinned READMEs of TeaCache, FirstBlockCache, AdaptiveCache, the FBcache pack and TE-Speed. Relations: AdaptiveCache README, line 326 and line 328; block patches: nodes_, lines 1–3, at 3c80da7f…. The results: the cache-node test page.
Frequently asked questions
Which Turbo LoRA file applies to a 1344×768 T2V or I2V run?
minimax_h3_fl2v_turbo_4step_v1.0_768p_comfyui_bf16.safetensors. Its bound specification at 1344×768 is 4 steps and a shift of 6 for video and 3 for audio, used as a set with the file name.
How much faster was the Turbo LoRA on your RTX 3060?
On the same machine and workload, the paired wall-time range was 4.113×–4.132×: Turbo off took 2,175.5 s and 2,176.2 s at 20 steps, Turbo on took 526.7 s, 528.9 s and 528.6 s at 4 steps. The range is published as a pairing, not an average.
Does the Turbo LoRA reduce VRAM or make an 8GB card work?
Our run did not establish a reliable peak-VRAM reduction: Turbo-off peaks were 11,023 and 10,863 MiB against Turbo-on peaks of 11,185, 10,479 and 10,895 MiB. All three Turbo peaks were above 8,192 MiB; this was not an 8GB-card test, so no 8GB claim is made in either direction.
Does minimax_h3_turbo_4step_pruned_comfyui.safetensors exist?
Not in the official Comfy-Org packaging. RunComfy's download anchor targets the exact /H3/minimax_h3_turbo_4step_pruned_comfyui.safetensors resolve URL, which returns 404; the separate official loras/ tree contains only the three _comfyui_bf16 files above. The same-named file does exist in the third-party drbaph conversion repository (620,285,648 bytes at the pinned revision, checked 2026-08-27), but it is a Larryvrh-derived pruned/curve-form conversion whose own metadata warns that four-step behaviour may be degraded or broken, so it is not an official equivalent.
Is fal's H3 Max Turbo the same thing as this Turbo LoRA?
No. H3 Max Turbo is a hosted fal endpoint released as a preview on September 2, 2026 and priced at half the H3 Max rate; it is a distilled model served by fal, and its API schema listed no LoRA input when checked on September 3, 2026. The Turbo LoRA on this page is a downloadable file applied to the open-weight MiniMax H3 inside a local ComfyUI graph.